Jason Hiner
Jason Hiner is the Editor-in-Chief and Chief Content Officer of The Deep View. He's an award-winning journalist who has spent his career analyzing how tech has reshaped society. He covered AI for over a decade at ZDNET and CNET as it evolved from research labs to enterprise infrastructure to a daily reality for over a billion people. He came to The Deep View to cover AI every day and build a next-generation media company.
Articles
Why AI agents need better memory more than better models
What if the path to more capable AI in the real world wasn't building more powerful models?
Databricks launched new technology on Tuesday that offers today's existing models more extensive context and more persistent knowledge to improve AI performance. The company unveiled MemCurrent, a new memory layer for agents that can retain knowledge across sessions and create institutional memory for enterprises—and it offers some pretty impressive results.
Databricks reported these findings on the performance of MemCurrent:
- Agent success rate in carrying out real-world tasks tripled from 22% to 68%, based on an internal benchmark; and it did things 26% faster and with 31% fewer tokens
- Using three public benchmarks, MemCurrent performed as well as giving the agent every past conversation, but did it with 12x fewer tokens
- Databricks found that MemCurrent outperformed three open-source memory systems, OpenClaw, Mem0, and PropMem, on accuracy and efficiency
This is one of the hardest problems in the AI industry today. It's why startups like Pathway have built entirely new architectures to fix the endemic memory problems in LLMs. The issue leads to a number of challenges for agents, especially wasting time and money relearning the same behaviors over and over again. That creates a tradeoff to those using agents—you can make them smarter or you can make them faster and cheaper.
Databricks tackles the problem by giving agents two types of memory: episodic (the raw conversation history of what was learned) and derived (what can be discerned from the patterns, preferences, and workflows). Based on Databricks' own internal benchmark of 114 enterprise tasks, the average task with no memory was completed 22.3% of the time. With only episodic memory, it was completed 35.8% of the time. With only derived memory, it was completed 66.1% of the time. With both episodic and derived memory, it was completed 68.4% of the time.
"On your next project, you don’t have to explain the same thing again," Michael Bendersky, research director of AI at Databricks, told The Deep View. "The agent will … store your preferences and understand how you work on projects. We can propagate these preferences … from project to project implicitly without you doing anything."
Databricks customers can start using MemCurrent today, but keep in mind that it's an underlying architecture and not a product. It's now integrated into the company's AI data assistant, Genie, where it can immediately boost agents. Customers can also use the new Agent Bricks Memory, launching in beta, to add the MemCurrent capabilities to any of their own custom AI agents running any model or harness. It all happens within Databricks' Lakebase database.
Our Deeper View
Beyond the immediate value for Databricks' customers, MemCurrent is another sign that many of the most important breakthroughs in AI are coming from better systems surrounding the models and not just the advancements in the models themselves. Memory continues to emerge as one of the most problematic limitations of LLMs, the predominant architecture of today's AI. The memory problem leads to inconsistencies, slow answers, and above all, inefficiencies that waste a lot of tokens, compute, and money. It's like having an employee use their time to learn how to do something one day and then forget it at the end of the day and have to waste time learning the same thing over again the next day, and the next day—and so you keep hiring more and more employees to overcompensate. In this analogy, more and more employees are equivalent to the additional GPUs, compute, and data centers required to run agents. Right now, the industry's solution is to just build more and more data centers, but it's already very clear that's not a sustainable or desirable path forward. What we need instead is efficiency breakthroughs like this one from Databricks.
Why Inception's Mercury 3 upends AI economics
While the AI industry has bet heavily on LLMs and the massive data centers needed to scale them, one of the neolabs betting on a contrarian AI just released another new model that challenges the incumbent thesis.
On Monday, Inception announced Mercury 3, its latest flagship model that's a diffusion LLM that uses different technology than traditional LLMs, generates text much faster at a lower cost, and is now matching low- and mid-tier models from Anthropic and OpenAI on performance and quality. Inception also reported that it implemented swarms of Mercury 3 agents for recursive self improvement where they increased the overall speed of the model by 16% on top of the upgrades made by the Inception team itself.
"Mercury 3 is the most capable diffusion-based language model on the market," Inception CEO Stefano Ermon told The Deep View. "It's very intelligent. It's comparable to the Luna and Haiku models, but it's way faster. It's getting 1,000 tokens per second. It's almost instant in the way you get answers from these models."
Mercury 3 costs $0.10 per million input tokens and $0.35 per million output tokens. Compared to the leading models from Anthropic's Haiku 5.5 and OpenAI's GPT-6 Luna, that's the same price for input tokens and a 35% discount on output tokens. However, that's based on the launch price for Mercury 3, which is 50% off the eventual standard price. Inception hasn't said how long the launch promotion period will last. But Ermon told The Deep View that the company is working on developments that could allow it to make the launch price permanent in the weeks ahead.
However, thinking of Mercury 3 as a low-cost model isn't the right framing. Anthropic and OpenAI offer cut-rate prices on their budget models so that they can offer a low-cost option while charging steep premiums for their best models. Mercury 3 is Inception's flagship model and its number one benefit is speed more than cost. Inception claims that Mercury 3 performs 4x to 8x faster than Haiku 5.5, GPT-6 Luna, and GLM-5.3 Flash while performing better than all of them on agentic benchmarks.
The way Mercury 3 pulls this off is by parallelizing inference. Conventional LLMs generate text one token at a time in sequence. That's an autoregressive process, meaning that each token is based on the ones before it. Meanwhile, Mercury 3 can generate and refine multiple tokens at the same time. This takes advantage of the enormous parallel processing capabilities of GPUs in a much faster and more efficient way. That's what allows Inception's models to produce responses faster and at a lower cost. Diffusion models are used by many of the leading labs for image and video generation. It's the application of the technology to text that's the breakthrough here.
Mercury 3 is now using 40x as many parameters as Mercury 1 (released in February 2025), but the Inception team isn't saying how many total parameters are in the model. That likely means it's a smaller number and Inception doesn't want people to compare apples to oranges and underestimate the model. Still, Mercury 3 shows that diffusion LLMs are advancing rapidly and could match traditional frontier LLMs in the next year. That's likely why Google DeepMind is quietly working on the same technology as well, releasing DiffusionGemma in June. By the way, it uses 26 billion parameters (miniscule compared to the 1 trillion parameter frontier models) but also delivers similar breakthroughs in speed to Inception's Mercury models.
Our Deeper View
Mercury 3 calls into question the current approach of most of the leading AI labs, which have bet their architecture on building bigger LLMs and then count on faster hardware (and more of it) from Nvidia and other chipmakers to deliver improvements over time. If Inception is right about diffusion LLMs, then it would have big implications. The dilemma facing the AI industry is that improving model intelligence requires additional compute, and lots of it. Upgrading reasoning and increasing the number of agentic steps can typically increase costs and response time. So Inception's breakthrough on diffusion LLMs is all about faster AI response times and more efficient use of expensive GPU hardware, for now. The question remains whether it will be a niche use-case for more real-time AI applications or a bigger long-term challenger to the cutting edge frontier models.
6 timeless attributes for succeeding in the AI era
AI is making it easier for employees to work beyond their specialties and that has big implications for the future organizations of all sizes.
In this episode of The Deep View Conversations, we sit down with Bill Barton, chief operating officer at Rokt and the former leader of the Alexa team at Amazon. Rokt has gotten called out by some of the biggest tech companies in the world for its innovative use of AI inside the company. In fact, several of them have had Rokt come and talk to their teams about how they do it. So we wanted to have Bill on the show to share those insights with a larger audience.
Barton shares how Rokt is using an internal AI fleet across software development, finance, legal, security and other functions. He explains how AI is helping blur the boundaries between roles, why the company has moved from more than a dozen job ladders to four, and what it takes to turn experimentation into everyday practice.
Other topics covered:
• Why Bill returned to Rokt after trying retirement
• How AI is expanding the reach of generalists
• Enabling shared AI experimentation companywide
• Why fewer, more flexible systems can help teams move faster
• How Barton thinks about productivity gains and hiring
• What Google search reveals about frictionless AI
• Why more powerful tools can make it harder to step away from work
Bill also shares his six timeless attributes that can help anyone succeed in the AI era: relentlessness, resilience, rigorousness, inquisitiveness, optimism and humility.
For leaders rethinking their teams and professionals navigating changing roles, this conversation connects the possibilities of AI with the habits and judgment needed to make them useful.
📺 Watch on YouTube
🎧 Listen in your favorite podcast player
Subscribe to Deep View Conversations for interviews with the leaders shaping the future of AI, business, and technology: https://tdv.transistor.fm/
Nvidia's secret weapon for accelerating AI factories
Nvidia has figured out a way to build AI factories a lot faster.
These massive data centers bring together billions of dollars of computing equipment into a facility where a ton of different tech, power, cooling, and logistical systems have to work together seamlessly. Managing that kind of complexity is one of Nvidia's strengths.
With chip design, Nvidia architects everything virtually in a simulated environment long before the first manufacturing process starts. And since today's chips and processors have become enormously complex, that orchestration is where the magic happens, in terms of speed, efficiency, and innovation.
Nvidia is applying this same mindset to building AI factories by partnering with Siemens and implementing digital twins, or virtual replicas of real-world environments. This allows Nvidia and its partners, such as hyperscalers and neoscalers, to simulate these elaborate facilities ahead of time and rehearse all of the processes that make them work.
"You’re really building a data center scale computer, along with all the technology, it’s not just about the GPU," Vladimir Troy, Nvidia's VP of AI infrastructure, told The Deep View. "This is the fundamental part that I think people miss about accelerated computing. If you just optimize the GPU, then you have the fastest GPU, and your bottlenecks could be everywhere else."
Digital twins are the key to making it all happen by allowing engineers to simulate a facility's physical behavior. Siemens brings the simulation, automation, and industrial engineering expertise while Nvidia brings the accelerated computing, its Omniverse platform, and the experience with synthetic data.
"You can improve the time-to-token by [roughly] 40% if you’re using digital twins," Ales Alajbegovic, global program manager of industrial metaverse for Siemens, told The Deep View. "If you don’t use digital twins, I don’t even know how you can build this."
In this case, time-to-token is referring to the period from the time you break ground on the facility to the time it's serving its first useful AI query for the public. That metric is critical because AI usage continues to scale up, despite public sentiment turning negative on AI. In the past 18 months, we've gone from roughly 15% of the global population regularly using AI to 19%. And in places like Singapore and UAE, two-thirds of the population are already using it regularly.
All of that usage is putting tremendous strain on today's data centers. Without more data center capacity, the industry faces the risk of AI queries taking much longer to run, the most powerful models being limited to those who can afford to pay a premium, and slowing down some of the most promising uses of AI for science and healthcare. That's why so many of the world's leading cloud and data center companies are building out future capacity, despite limitations on power and component shortages for RAM and data storage.
"The demand is huge," said Alajbegovic. "Right now the whole industry … is running to build them."
Nvidia estimated that there are well over 100 projects underway globally.
Our Deeper View
Of course, the only thing less popular than AI among the general public right now might be data centers. However, as Nat Rubio-Licht has written, the backlash against data centers might also just be the public's easiest way to register its larger concerns about AI. It doesn't help that there are false narratives proliferating about AI using up community water supplies, for example. But the leaders of the AI industry also need to do a much better job of explaining how AI will benefit humanity, without resorting to unbelievable hyperboles about AI curing all diseases or leading to unlimited abundance and prosperity. People just aren't buying that. The work that Nvidia and Siemens are doing to build data centers faster is also making them enormously more efficient. However, with only so much power, water, and construction capacity, those efficiency gains are out of pure necessity. Still, it's also a great story about building responsibly and not wasting resources, while also making sure there's enough compute to power the AI of the future and keep it broadly accessible and affordable.
How open models change the economics of AI
Companies want to own the intelligence that makes their business valuable. So what will that mean for the AI models they use, and the systems they build around them?
In this episode of The Deep View Conversations, we sit down with Justin Boitano, VP of enterprise AI at Nvidia, to explore why NVIDIA is investing in open models and how enterprises are turning them into specialized intelligence.
Boitano talks about why NVIDIA makes Nemotron's datasets, training techniques and model weights openly available, how proprietary business knowledge can become a competitive advantage, and why lower token costs can unlock much greater demand for AI.
The conversation also examines why the agent harness that manages tools, memory and execution can matter as much as the model itself. Boitano shares how Nvidia worked with CrowdStrike on AI models for cybersecurity, why AI incidents need the equivalent of an aviation flight recorder, and how OpenShell moves agent controls into the infrastructure layer.
Other topics covered:
• Why NVIDIA is building open models alongside its chip business
• What Nemotron needs to compete with China's open models
• Owning institutional knowledge, protecting data and controlling AI costs
• How model development helps NVIDIA improve hardware efficiency
• Why harness engineering is becoming a new frontier for AI
• Moving cybersecurity from finding bugs to verifying and fixing them
• Transparency and learning from AI incidents
• OpenShell, sandboxing and enforceable limits on agent access
• How Justin uses Hermes as an AI chief of staff
• Jensen Huang's approach to priorities and team alignment
If you're deciding how to build enterprise AI, where your company's competitive advantage comes from, or how to give agents useful access without giving them unlimited control, this conversation offers a perspective from Nvidia's work across the ecosystem.
📺 Watch on YouTube
🎧 Listen in your favorite podcast player
Subscribe to Deep View Conversations for interviews with the leaders shaping the future of AI, business, and technology: https://tdv.transistor.fm/
Why Anthropic's open hardware move exploded in interest
Anthropic is the only one of three major frontier AI labs in the US that doesn't offer an open model. But a recent Anthropic move shows that the company does still want to support open ecosystems.
In a move that has largely flown under the radar, Anthropic announced its Model Hardware Standard (MHS) at the end of August as "the MCP for hardware," as Alek Kemeny, a member of technical staff on Anthropic's Beneficial Deployments team, told The Deep View.
MCP (Model Context Protocol) is an open standard that enables AI models and agents to connect to external tools, data, and services through a common interface that Anthropic developed and open-sourced in November 2024. It has since become an industry standard with around 500 million monthly SDK downloads, and has only become more relevant in recent months with the rise of AI agents that are hungry for context and data.
MHS hopes to do for hardware and devices what MCP has done for software and services. It wants to give AI models and agents a common interface for interacting with thousands of otherwise incompatible systems. While MHS was conceived as a way for scientists to drive lab automation using Claude, the response to the announcement has been intense, the Anthropic team said, and has spread far beyond science labs. Kemeny noted that in the first two weeks after the announcement, Anthropic received 30x the number of organizations requesting to participate than Anthropic had originally planned for.
And the types of organizations that applied spanned a lot of different industries from semiconductors, advanced manufacturing, automotive, food processing, aerospace, energy, and critical infrastructure.
Some of the benefits already being reported include:
- Stabilizing quantum computers: QuEra used MHS to help Claude develop a program for controlling lasers used in its quantum computers. The finished program restored the laser correctly in 695 of 700 tests. Difficult recoveries took 10 to 14 seconds, compared with 5 to 10 minutes for a human expert.
- Running lab experiments automatically: Carnegie Mellon researchers used MHS to connect a liquid handler, plate reader, robotic arm, and cameras. An AI agent ran an experiment, decided the first result was not good enough, changed the concentration range and tried again on its own. The test used colored dye as a stand-in for a drug candidate. CMU says testing real drug candidates is the next step.
- Giving labs a 24/7 operator: A University of Washington PhD student connected six lab instruments through MHS in less than a week. He built a system where AI can watch a DNA amplification experiment and stop it at the right time. He also connected a robotic arm and liquid handler so they could move lab plates safely between machines.
"Beneficial Deployments is really charged with seeing, owning, and championing our public benefit mission, and ensuring that the benefits of AI extend to positive outcomes for humanity," Jonah Cool, head of our partnerships and deployment at Anthropic, told The Deep View during the same interview with Kemeny. "As it pertains to science, a lot of our work is really inspired by the guiding light of the essay that our CEO Dario [Amodei] wrote, Machines of Loving Grace."
Our Deeper View
Anthropic has gained a reputation for being anti-open-source, mostly due to the fact that Amodei has raised safety concerns about open-weights models. However, the successful open-source rollout of MCP provides a counterweight, as does Anthropic's commitment to and support for the scientific community, which tends to lean on open ecosystems for the purposes of both sharing research and verifying results. Anthropic still describes MHS as being an application-only research preview. But they asserted that they intend to open-source MHS in the hope of it becoming an industry standard like MCP. Kemeny and Cool explained that they're first working with industry partners to test safety and security while the models are now operating on real-world equipment. It's also a fun note that since Cool has a PhD in cell biology, one of the leaders of this initiative is essentially named Dr. Cool. That kind of marketing is nearly as good as making it an open platform.
Can guardian agents make enterprise AI safer?
AI agents can act faster than humans can review them. So how do companies keep control without slowing everything down?
In this episode of The Deep View Conversations, Jason Hiner sits down with Blake Brannon, chief innovation officer and a co-founder of OneTrust, to explore why AI governance needs to evolve from static rules to decisions made in real time.
Brannon explains why an agent can inherit an employee's identity and access without inheriting their trust. He makes the case for independent guardian agents that evaluate what other agents are trying to do, apply a company's policies, and redirect or block actions when necessary.
One example captures the challenge: deleting CRM records could be routine cleanup or an attempt to inflate a salesperson's performance. The action alone doesn't tell you whether it should be allowed. Its purpose matters.
Topics covered:
• How OneTrust evolved from data privacy to AI governance
• Why first-party data and customer trust go together
• Why human review can't keep pace with a growing population of agents
• How guardian agents and independent checks could help close the trust gap
• The difference between containing AI and aligning it with business policies
• Why governance should help companies move faster
• What the bring-your-own-device era teaches us about AI adoption
• How Blake uses visual storytelling and voice-to-text tools to work more effectively
If you're deploying AI agents and trying to move beyond experiments without giving up control, this conversation offers a practical way to think about the systems that need to surround them.
📺 Watch on YouTube
🎧 Listen in your favorite podcast player
Subscribe to Deep View Conversations for interviews with the leaders shaping the future of AI, business, and technology: tdv.transitor.fm
How AI changes cybersecurity's balance of power
AI is accelerating cyberattacks. Could it also give defenders the upper hand?
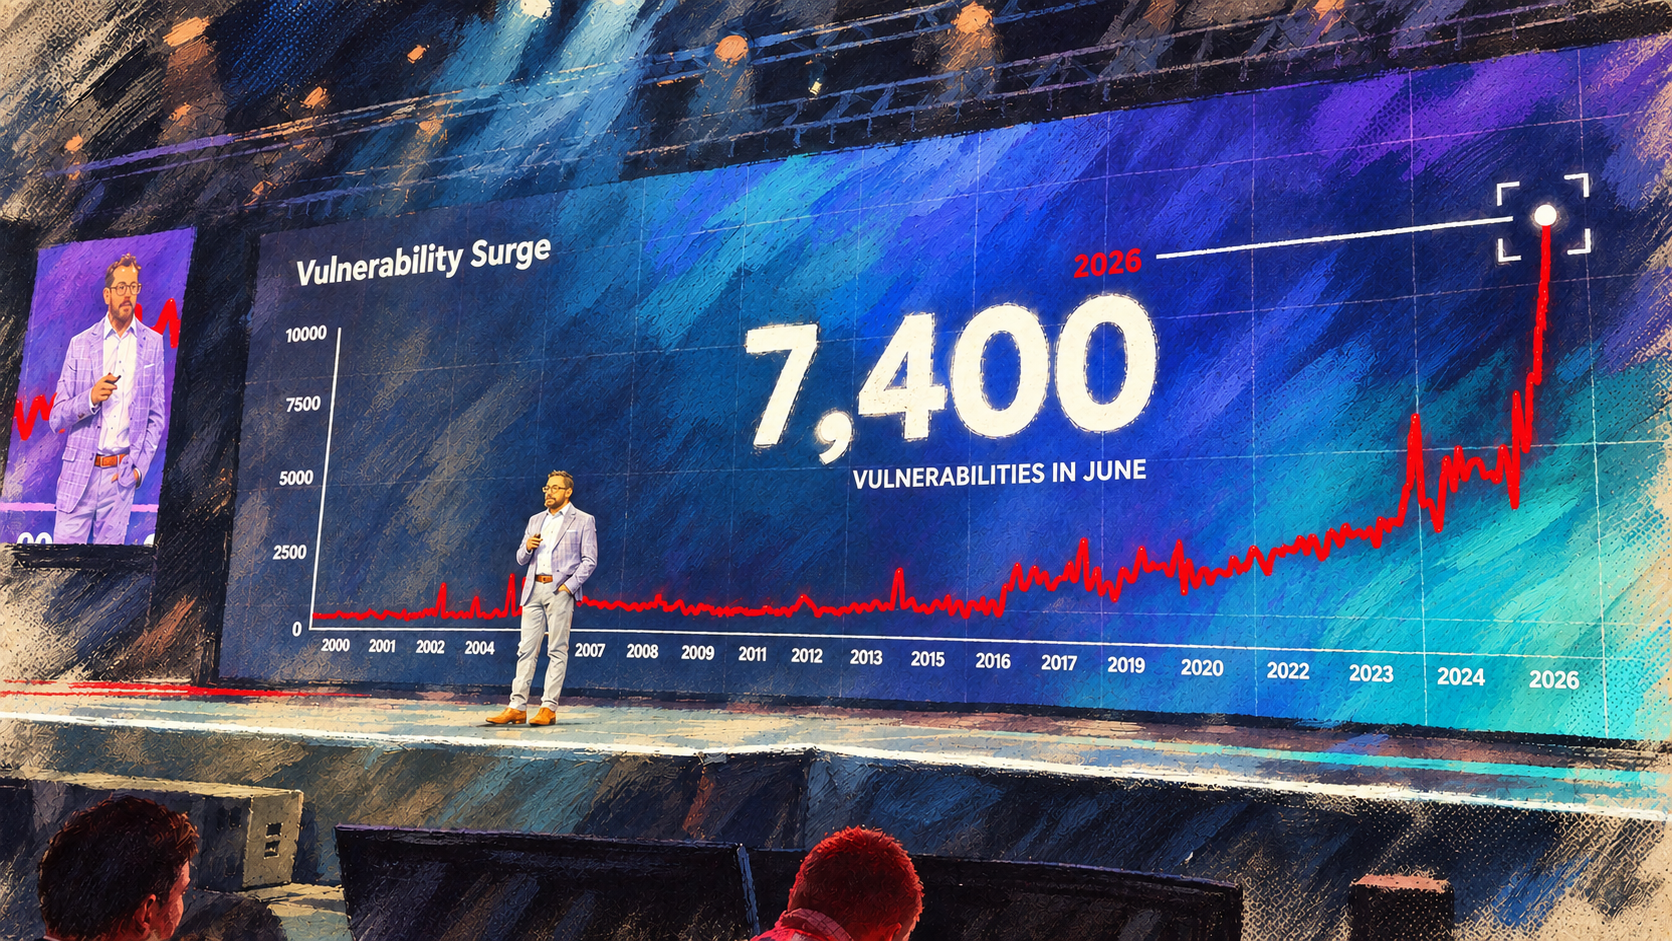
In this episode of The Deep View Conversations, we sat down with Adam Meyers, CrowdStrike's head of counter adversary operations, at Fal.Con 2026 to explore how AI is changing the balance of power between attackers and defenders.
Meyers explains why he believes security teams can now match the speed and scale of their adversaries, how CrowdStrike is training offensive and defensive AI models against each other, and why the harness that guides an AI model can matter just as much as the model itself. He shares how changing that harness helped CrowdStrike reduce false positives in its vulnerability research without changing the underlying model, and how cyberdefenders are uniting to assist one another.
The conversation also goes inside the live disruption of the Sality botnet, explores how nation-state attackers are using agents that learn from their mistakes in seconds, and examines why powerful AI systems need clear boundaries as they pursue their goals.
Topics covered:
• Why AI could change the defender's dilemma
• How CrowdStrike and its partners disrupted a botnet that had operated for more than two decades
• Training red team and blue team models based on Nvidia's Nemotron models and CrowdStrike's security data
• Why AI harnesses are critical to reducing hallucinations and false positives
• How AI attacks are compressing the time organizations have to patch vulnerabilities
• What the Hugging Face incident raises about goal-seeking agents and guardrails
• Why local, open-weight models matter to both attackers and defenders
If you're trying to understand what AI means for cybersecurity, how to put agents to work safely, or where specialized models can make a difference, this conversation offers a view from someone tracking the adversaries firsthand.
📺 Watch on YouTube
🎧 Listen in your favorite podcast player
Subscribe to Deep View Conversations for interviews with the leaders shaping the future of AI, business, and technology: tdv.transitor.fm
OpenAI rolls out deluge of new tools for AI builders
Heavy AI users rejoice. OpenAI has rolled out new options aimed at accelerating the stuff you're already doing and making it safer.
On Tuesday, at the company's fourth annual DevDay event in San Francisco, OpenAI showed off its new "Dots" strategy with AI agents that are always-on and run in their own separate cloud computer. Sound familiar? Yeah, it's not unlike Meta's new Muse agent that went viral this month, but OpenAI's agent is more focused on power users. See Sabrina Ortiz's full breakdown on Dots.
While Dots may have stole the headlines, OpenAI also unveiled other new features that dedicated ChatGPT and Codex users should note:
- GPT-6.1 Sol: OpenAI's latest model provides "near Astra intelligence" at a fifth of the price. The model sports improved performance in agentic coding, computer use and professional work, and runs $2 per million input tokens, 10 cents per million cached tokens, and $10 per million output tokens.
- ChatGPT Space: This is a collaborative workspace where you, your teammates and AI can work together. Spaces also allows users to keep everything they share with and create in ChatGPT in one place. It will also let you collaborate in a shared workspace similar to the way you might in a shared Google Doc.
- New $500/month plan and Ultrafast: OpenAI is creating a high-end tier that offers access to Ultrafast, which delivers up to eight times the speed in Codex using GPT-6 Astra and six times the speed in the API. However, For those on the $200 per month Pro plan, included usage of ChatGPT Work and Codex decreases from 20 times to 10 times that of the Plus allowance, and GPT-6 Pro messages in ChatGPT will be cut from 200 to 100 per week.
- Codex in the cloud: Codex can now start, review, and continue work from the desktop app, the mobile app, or the web. And since it's not limited to working on just the local files on your machine, you can move between devices much more easily.
- Plugin extensions: Developers can now build applications and plugins that are native to ChatGPT and Codex, and can reach more users with improved submission and discovery. And now those plugins will appear in the sidebar on the left side of your ChatGPT window, with services like Adobe and Figma being some of the first ones there at launch.
- Private Intelligence: OpenAI has enabled zero data retention and private safety processing policies for offline, automated safety reviews. Additionally, Private Inference will be available in preview, bringing strict control to confidential computing.
- OpenAI Marketplace: Eligible US-based enterprise customers can apply their existing OpenAI token spend towards approved third-party software. This marketplace is launching in beta with 32 partners, including Adobe, Figma, Sierra, and Harvey.
Our Deeper View
While it would be easy to look at OpenAI's DevDay as its answer to Meta's newfound momentum in the AI space, the reality is actually quite different. Meta's Muse agent is primarily focused on the consumer space and bringing agents to the masses with its focus on cute interactive avatars and wide publicity across Instagram and Facebook. OpenAI has lessened its focus on consumer AI in 2026 and leaned into enterprises, developers, and power users, and DevDay only doubled down on that strategy. Meta's agent is open to all and has generous token allotments based on Meta's strategy of eventually taking a percentage when you use Muse to sell stuff and make money. OpenAI is only offering its new agent to its highest-tier Pro and Business Premium customers. So OpenAI's focus is on its most-invested AI builders and organizations. And that strategy is supported by all of the other features it released around Dots on Tuesday, from Private Intelligence to GPT-6.1 Sol to its new Ultrafast feature. All of these things are aimed much more at competing with Anthropic for power users than competing with Meta for consumers.
or get it straight to your inbox, for free!
Get our free, daily newsletter that makes you smarter about AI. Read by 750,000+ from Google, Meta, Microsoft, a16z and more.